

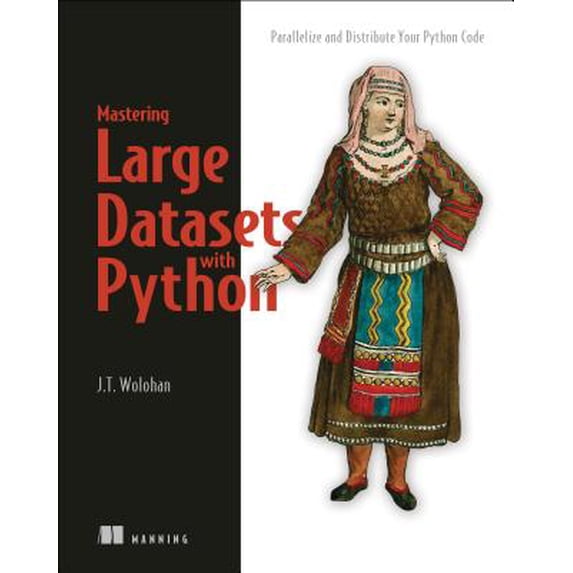
Mastering Large Datasets with Python : Parallelize and Distribute Your Python Code (Edition 1) (Paperback)
(No ratings yet)
Key item features
Summary
Modern data science solutions need to be clean, easy to read, and scalable. In Mastering Large Datasets with Python, author J.T. Wolohan teaches you how to take a small project and scale it up using a functionally influenced approach to Python coding. You’ll explore methods and built-in Python tools that lend themselves to clarity and scalability, like the high-performing parallelism method, as well as distributed technologies that allow for high data throughput. The abundant hands-on exercises in this practical tutorial will lock in these essential skills for any large-scale data science project.
About the technology
Programming techniques that work well on laptop-sized data can slow to a crawl—or fail altogether—when applied to massive files or distributed datasets. By mastering the powerful map and reduce paradigm, along with the Python-based tools that support it, you can write data-centric applications that scale efficiently without requiring codebase rewrites as your requirements change.
About the book
Mastering Large Datasets with Python teaches you to write code that can handle datasets of any size. You’ll start with laptop-sized datasets that teach you to parallelize data analysis by breaking large tasks into smaller ones that can run simultaneously. You’ll then scale those same programs to industrial-sized datasets on a cluster of cloud servers. With the map and reduce paradigm firmly in place, you’ll explore tools like Hadoop and PySpark to efficiently process massive distributed datasets, speed up decision-making with machine learning, and simplify your data storage with AWS S3.What's inside
For Python programmers who need to work faster with more data.
About the author
J. T. Wolohan is a lead data scientist at Booz Allen Hamilton, and a PhD researcher at Indiana University, Bloomington.
Table of Contents:
PART 1
1 ¦ Introduction
2 ¦ Accelerating large dataset work: Map and parallel computing
3 ¦ Function pipelines for mapping complex transformations
4 ¦ Processing large datasets with lazy workflows
5 ¦ Accumulation operations with reduce
6 ¦ Speeding up map and reduce with advanced parallelization
PART 2
7 ¦ Processing truly big datasets with Hadoop and Spark
8 ¦ Best practices for large data with Apache Streaming and mrjob
9 ¦ PageRank with map and reduce in PySpark
10 ¦ Faster decision-making with machine learning and PySpark
PART 3
11 ¦ Large datasets in the cloud with Amazon Web Services and S3
12 ¦ MapReduce in the cloud with Amazon’s Elastic MapReduce
Modern data science solutions need to be clean, easy to read, and scalable. In Mastering Large Datasets with Python, author J.T. Wolohan teaches you how to take a small project and scale it up using a functionally influenced approach to Python coding. You’ll explore methods and built-in Python tools that lend themselves to clarity and scalability, like the high-performing parallelism method, as well as distributed technologies that allow for high data throughput. The abundant hands-on exercises in this practical tutorial will lock in these essential skills for any large-scale data science project.
About the technology
Programming techniques that work well on laptop-sized data can slow to a crawl—or fail altogether—when applied to massive files or distributed datasets. By mastering the powerful map and reduce paradigm, along with the Python-based tools that support it, you can write data-centric applications that scale efficiently without requiring codebase rewrites as your requirements change.
About the book
Mastering Large Datasets with Python teaches you to write code that can handle datasets of any size. You’ll start with laptop-sized datasets that teach you to parallelize data analysis by breaking large tasks into smaller ones that can run simultaneously. You’ll then scale those same programs to industrial-sized datasets on a cluster of cloud servers. With the map and reduce paradigm firmly in place, you’ll explore tools like Hadoop and PySpark to efficiently process massive distributed datasets, speed up decision-making with machine learning, and simplify your data storage with AWS S3.What's inside
- An introduction to the map and reduce paradigm
- Parallelization with the multiprocessing module and pathos framework
- Hadoop and Spark for distributed computing
- Running AWS jobs to process large datasets
For Python programmers who need to work faster with more data.
About the author
J. T. Wolohan is a lead data scientist at Booz Allen Hamilton, and a PhD researcher at Indiana University, Bloomington.
Table of Contents:
PART 1
1 ¦ Introduction
2 ¦ Accelerating large dataset work: Map and parallel computing
3 ¦ Function pipelines for mapping complex transformations
4 ¦ Processing large datasets with lazy workflows
5 ¦ Accumulation operations with reduce
6 ¦ Speeding up map and reduce with advanced parallelization
PART 2
7 ¦ Processing truly big datasets with Hadoop and Spark
8 ¦ Best practices for large data with Apache Streaming and mrjob
9 ¦ PageRank with map and reduce in PySpark
10 ¦ Faster decision-making with machine learning and PySpark
PART 3
11 ¦ Large datasets in the cloud with Amazon Web Services and S3
12 ¦ MapReduce in the cloud with Amazon’s Elastic MapReduce
Specs
Publication date, January, 2020
Author, John T. Wolohan
Book format, Paperback
Genre, Computing & Internet
Pages, 312
Age group, Adult
Publication date
January, 2020
Author, John T. Wolohan
Author
John T. Wolohan
Book format, Paperback
Book format
Paperback
Genre, Computing & Internet
Genre
Computing & Internet
Pages, 312
Pages
312
Age group, Adult
Age group
Adult
About this item
Product details
Summary
Modern data science solutions need to be clean, easy to read, and scalable. In Mastering Large Datasets with Python, author J.T. Wolohan teaches you how to take a small project and scale it up using a functionally influenced approach to Python coding. You'll explore methods and built-in Python tools that lend themselves to clarity and scalability, like the high-performing parallelism method, as well as distributed technologies that allow for high data throughput. The abundant hands-on exercises in this practical tutorial will lock in these essential skills for any large-scale data science project. Purchase of the print book includes a free eBook in PDF, Kindle, and ePub formats from Manning Publications. About the technology
Programming techniques that work well on laptop-sized data can slow to a crawl--or fail altogether--when applied to massive files or distributed datasets. By mastering the powerful map and reduce paradigm, along with the Python-based tools that support it, you can write data-centric applications that scale efficiently without requiring codebase rewrites as your requirements change. About the book
Mastering Large Datasets with Python teaches you to write code that can handle datasets of any size. You'll start with laptop-sized datasets that teach you to parallelize data analysis by breaking large tasks into smaller ones that can run simultaneously. You'll then scale those same programs to industrial-sized datasets on a cluster of cloud servers. With the map and reduce paradigm firmly in place, you'll explore tools like Hadoop and PySpark to efficiently process massive distributed datasets, speed up decision-making with machine learning, and simplify your data storage with AWS S3. What's inside
For Python programmers who need to work faster with more data. About the author
J. T. Wolohan is a lead data scientist at Booz Allen Hamilton, and a PhD researcher at Indiana University, Bloomington. Table of Contents: PART 1 1 ] Introduction 2 ] Accelerating large dataset work: Map and parallel computing 3 ] Function pipelines for mapping complex transformations 4 ] Processing large datasets with lazy workflows 5 ] Accumulation operations with reduce 6 ] Speeding up map and reduce with advanced parallelization PART 2 7 ] Processing truly big datasets with Hadoop and Spark 8 ] Best practices for large data with Apache Streaming and mrjob 9 ] PageRank with map and reduce in PySpark 10 ] Faster decision-making with machine learning and PySpark PART 3 11 ] Large datasets in the cloud with Amazon Web Services and S3 12 ] MapReduce in the cloud with Amazon's Elastic MapReduce
Modern data science solutions need to be clean, easy to read, and scalable. In Mastering Large Datasets with Python, author J.T. Wolohan teaches you how to take a small project and scale it up using a functionally influenced approach to Python coding. You'll explore methods and built-in Python tools that lend themselves to clarity and scalability, like the high-performing parallelism method, as well as distributed technologies that allow for high data throughput. The abundant hands-on exercises in this practical tutorial will lock in these essential skills for any large-scale data science project. Purchase of the print book includes a free eBook in PDF, Kindle, and ePub formats from Manning Publications. About the technology
Programming techniques that work well on laptop-sized data can slow to a crawl--or fail altogether--when applied to massive files or distributed datasets. By mastering the powerful map and reduce paradigm, along with the Python-based tools that support it, you can write data-centric applications that scale efficiently without requiring codebase rewrites as your requirements change. About the book
Mastering Large Datasets with Python teaches you to write code that can handle datasets of any size. You'll start with laptop-sized datasets that teach you to parallelize data analysis by breaking large tasks into smaller ones that can run simultaneously. You'll then scale those same programs to industrial-sized datasets on a cluster of cloud servers. With the map and reduce paradigm firmly in place, you'll explore tools like Hadoop and PySpark to efficiently process massive distributed datasets, speed up decision-making with machine learning, and simplify your data storage with AWS S3. What's inside
- An introduction to the map and reduce paradigm
- Parallelization with the multiprocessing module and pathos framework
- Hadoop and Spark for distributed computing
- Running AWS jobs to process large datasets
For Python programmers who need to work faster with more data. About the author
J. T. Wolohan is a lead data scientist at Booz Allen Hamilton, and a PhD researcher at Indiana University, Bloomington. Table of Contents: PART 1 1 ] Introduction 2 ] Accelerating large dataset work: Map and parallel computing 3 ] Function pipelines for mapping complex transformations 4 ] Processing large datasets with lazy workflows 5 ] Accumulation operations with reduce 6 ] Speeding up map and reduce with advanced parallelization PART 2 7 ] Processing truly big datasets with Hadoop and Spark 8 ] Best practices for large data with Apache Streaming and mrjob 9 ] PageRank with map and reduce in PySpark 10 ] Faster decision-making with machine learning and PySpark PART 3 11 ] Large datasets in the cloud with Amazon Web Services and S3 12 ] MapReduce in the cloud with Amazon's Elastic MapReduce
Summary
Modern data science solutions need to be clean, easy to read, and scalable. In Mastering Large Datasets with Python, author J.T. Wolohan teaches you how to take a small project and scale it up using a functionally influenced approach to Python coding. You’ll explore methods and built-in Python tools that lend themselves to clarity and scalability, like the high-performing parallelism method, as well as distributed technologies that allow for high data throughput. The abundant hands-on exercises in this practical tutorial will lock in these essential skills for any large-scale data science project.
About the technology
Programming techniques that work well on laptop-sized data can slow to a crawl—or fail altogether—when applied to massive files or distributed datasets. By mastering the powerful map and reduce paradigm, along with the Python-based tools that support it, you can write data-centric applications that scale efficiently without requiring codebase rewrites as your requirements change.
About the book
Mastering Large Datasets with Python teaches you to write code that can handle datasets of any size. You’ll start with laptop-sized datasets that teach you to parallelize data analysis by breaking large tasks into smaller ones that can run simultaneously. You’ll then scale those same programs to industrial-sized datasets on a cluster of cloud servers. With the map and reduce paradigm firmly in place, you’ll explore tools like Hadoop and PySpark to efficiently process massive distributed datasets, speed up decision-making with machine learning, and simplify your data storage with AWS S3.What's inside
For Python programmers who need to work faster with more data.
About the author
J. T. Wolohan is a lead data scientist at Booz Allen Hamilton, and a PhD researcher at Indiana University, Bloomington.
Table of Contents:
PART 1
1 ¦ Introduction
2 ¦ Accelerating large dataset work: Map and parallel computing
3 ¦ Function pipelines for mapping complex transformations
4 ¦ Processing large datasets with lazy workflows
5 ¦ Accumulation operations with reduce
6 ¦ Speeding up map and reduce with advanced parallelization
PART 2
7 ¦ Processing truly big datasets with Hadoop and Spark
8 ¦ Best practices for large data with Apache Streaming and mrjob
9 ¦ PageRank with map and reduce in PySpark
10 ¦ Faster decision-making with machine learning and PySpark
PART 3
11 ¦ Large datasets in the cloud with Amazon Web Services and S3
12 ¦ MapReduce in the cloud with Amazon’s Elastic MapReduce
Modern data science solutions need to be clean, easy to read, and scalable. In Mastering Large Datasets with Python, author J.T. Wolohan teaches you how to take a small project and scale it up using a functionally influenced approach to Python coding. You’ll explore methods and built-in Python tools that lend themselves to clarity and scalability, like the high-performing parallelism method, as well as distributed technologies that allow for high data throughput. The abundant hands-on exercises in this practical tutorial will lock in these essential skills for any large-scale data science project.
About the technology
Programming techniques that work well on laptop-sized data can slow to a crawl—or fail altogether—when applied to massive files or distributed datasets. By mastering the powerful map and reduce paradigm, along with the Python-based tools that support it, you can write data-centric applications that scale efficiently without requiring codebase rewrites as your requirements change.
About the book
Mastering Large Datasets with Python teaches you to write code that can handle datasets of any size. You’ll start with laptop-sized datasets that teach you to parallelize data analysis by breaking large tasks into smaller ones that can run simultaneously. You’ll then scale those same programs to industrial-sized datasets on a cluster of cloud servers. With the map and reduce paradigm firmly in place, you’ll explore tools like Hadoop and PySpark to efficiently process massive distributed datasets, speed up decision-making with machine learning, and simplify your data storage with AWS S3.What's inside
- An introduction to the map and reduce paradigm
- Parallelization with the multiprocessing module and pathos framework
- Hadoop and Spark for distributed computing
- Running AWS jobs to process large datasets
For Python programmers who need to work faster with more data.
About the author
J. T. Wolohan is a lead data scientist at Booz Allen Hamilton, and a PhD researcher at Indiana University, Bloomington.
Table of Contents:
PART 1
1 ¦ Introduction
2 ¦ Accelerating large dataset work: Map and parallel computing
3 ¦ Function pipelines for mapping complex transformations
4 ¦ Processing large datasets with lazy workflows
5 ¦ Accumulation operations with reduce
6 ¦ Speeding up map and reduce with advanced parallelization
PART 2
7 ¦ Processing truly big datasets with Hadoop and Spark
8 ¦ Best practices for large data with Apache Streaming and mrjob
9 ¦ PageRank with map and reduce in PySpark
10 ¦ Faster decision-making with machine learning and PySpark
PART 3
11 ¦ Large datasets in the cloud with Amazon Web Services and S3
12 ¦ MapReduce in the cloud with Amazon’s Elastic MapReduce
info:
We aim to show you accurate product information. Manufacturers, suppliers and others provide what you see here, and we have not verified it.
Specifications
Publication date
January, 2020
Author
John T. Wolohan
Book format
Paperback
Genre
Computing & Internet
Warranty
Warranty information
Please be aware that the warranty terms on items offered for sale by third party Marketplace sellers may differ from those displayed in this section (if any). To confirm warranty terms on an item offered for sale by a third party Marketplace seller, please use the 'Contact seller' feature on the third party Marketplace seller's information page and request the item's warranty terms prior to purchase.
Similar items you might like
Based on what customers bought
Building AI Systems with Python: Practical Machine Learning and Agentic Workflows with Python and Pytorch, (Paperback) $49.09
 $4909current price $49.09
Building AI Systems with Python: Practical Machine Learning and Agentic Workflows with Python and Pytorch, (Paperback)
Python Programming for Data Analysis, (Paperback) $60.84
 $6084current price $60.84
Python Programming for Data Analysis, (Paperback)
Master Python Using Version 3.11: Learn Python Like Never Before, (Paperback) $34.28
 $3428current price $34.28
Master Python Using Version 3.11: Learn Python Like Never Before, (Paperback)
Top 1% Python Developer Python for Beginners: Master the Basics of Python with Easy-to-Follow Visuals and get started quickly, Book 1, (Paperback) $29.99
 $2999current price $29.99
Top 1% Python Developer Python for Beginners: Master the Basics of Python with Easy-to-Follow Visuals and get started quickly, Book 1, (Paperback)
Chapman & Hall/CRC the Python Tidy Finance with Python, (Paperback) $67.67
 $6767current price $67.67
Chapman & Hall/CRC the Python Tidy Finance with Python, (Paperback)
Excel with Python Python in Excel: Automate, Analyze, and Accelerate Your Workflow, Book 1, (Paperback) $26.99
 $2699current price $26.99
Excel with Python Python in Excel: Automate, Analyze, and Accelerate Your Workflow, Book 1, (Paperback)
Python for Data Science and Machine Learning: The Only Book You Need to Master Python for DS and ML from Scratch: A Hand, (Paperback) $24.99
 $2499current price $24.99
Python for Data Science and Machine Learning: The Only Book You Need to Master Python for DS and ML from Scratch: A Hand, (Paperback)
Programming Techniques using Python: Have Fun and Play with Basic and Advanced Core Python (Paperback) $31.29
 $3129current price $31.29
Programming Techniques using Python: Have Fun and Play with Basic and Advanced Core Python (Paperback)
A Developer's Roadmap to Mastering Python, (Paperback) $79.00
 $7900current price $79.00
A Developer's Roadmap to Mastering Python, (Paperback)
GIS Programming in Practice: Automate, Analyze, and Visualize Spatial Data Using Python, GeoPandas, and Open-Source Tool, (Paperback) $28.37
 $2837current price $28.37
GIS Programming in Practice: Automate, Analyze, and Visualize Spatial Data Using Python, GeoPandas, and Open-Source Tool, (Paperback)
Mastering Python for Data Engineering: Transform and Manipulate Big Data with Python, (Paperback) $19.99
 $1999current price $19.99
Mastering Python for Data Engineering: Transform and Manipulate Big Data with Python, (Paperback)
Easy Learning Python and Design Patterns Easy Learning Python 3: Python for Beginner's Guide, Book 1, (Paperback) $39.90
 $3990current price $39.90
Easy Learning Python and Design Patterns Easy Learning Python 3: Python for Beginner's Guide, Book 1, (Paperback)
Python Full Stack Python Full Stack Unleashed From Code to Cloud VOL-IV, Book 4, (Paperback) $18.99
 $1899current price $18.99
Python Full Stack Python Full Stack Unleashed From Code to Cloud VOL-IV, Book 4, (Paperback)
Python for Data Science: Python and Data Science, (Paperback) $19.99
 $1999current price $19.99
Python for Data Science: Python and Data Science, (Paperback)
Python for Big Data and Analytics: Harness the Power of Python for Processing and Analyzing Large Data Sets, (Paperback) $19.99
 $1999current price $19.99
Python for Big Data and Analytics: Harness the Power of Python for Processing and Analyzing Large Data Sets, (Paperback)
Codecraft Mastering NumPy for Data Science and Machine Learning: A Complete Guide to High-Performance Array Computing in Python, (Paperback) $35.99
 $3599current price $35.99
Codecraft Mastering NumPy for Data Science and Machine Learning: A Complete Guide to High-Performance Array Computing in Python, (Paperback)
Hands-On Network Machine Learning with Python, (Paperback) $65.55
 $6555current price $65.55
Hands-On Network Machine Learning with Python, (Paperback)
Python-Powered Excel: Combining the strengths of Python and Excel for deliverables and complex tasks (English Edition), (Paperback) $39.95
 $3995current price $39.95
Python-Powered Excel: Combining the strengths of Python and Excel for deliverables and complex tasks (English Edition), (Paperback)
Dancing with Python: Learn to code with Python and Quantum Computing, (Paperback) $48.29
 $4829current price $48.29
Dancing with Python: Learn to code with Python and Quantum Computing, (Paperback)
Hands-On Web Scraping with Python - Second Edition: Extract quality data from the web using effective Python techniques, (Paperback) $46.99
 $4699current price $46.99
Hands-On Web Scraping with Python - Second Edition: Extract quality data from the web using effective Python techniques, (Paperback)
Customer ratings & reviews
0 out of 5 stars
This item does not have any reviews yet

Price when purchased online
More seller options (1)
Starting from $69.21
Related pages
- Computer Integrity
- Programming Blogs
- Php Laravel
- General Certification Guide Books
- Distributed Systems & Computing Books
- General Enterprise Applications Books
- Mathematical & Statistical Software Books
- Building Your Computer
- Open Source Books
- Use Code Python
- Computerintegrated Manufacturing
- JavaScript Programming Language Books